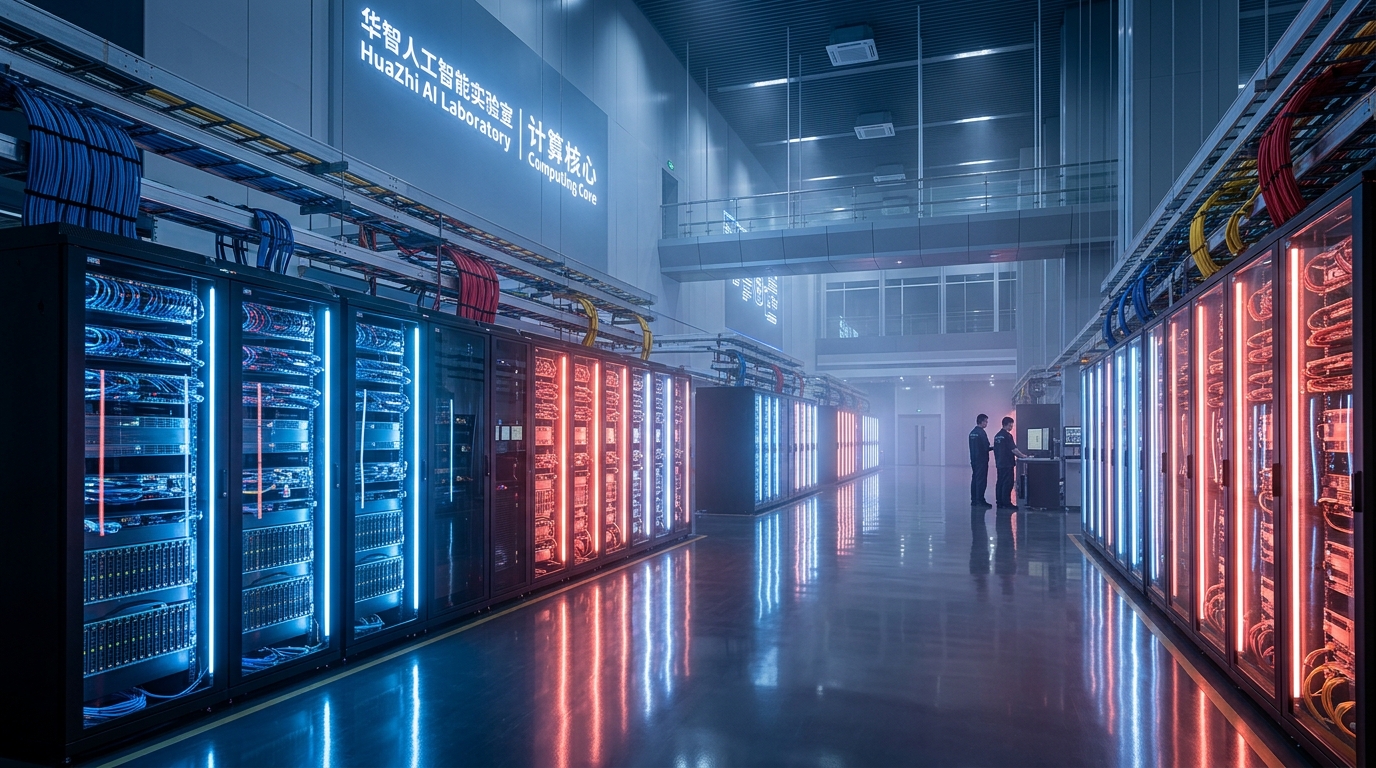
Inside a Chinese AI Lab’s Training Stack
A closer look at how leading Chinese labs are squeezing frontier-class results out of constrained hardware supply.
 Wei Lian🇨🇳 China Desk LeadJun 29, 2026 6m read
Constraints breed creativity, and nowhere is that clearer than in how China’s top labs approach large-scale training.
Doing more with less
Facing tighter access to the newest accelerators, several labs have leaned into aggressive quantization, custom communication kernels, and mixture-of-experts designs that activate only a fraction of parameters per token.
- Heavy use of MoE to cut active compute
- Communication-optimized training across large clusters
- Data curation treated as a first-class research problem
Why it matters globally
Many of these efficiency techniques are being published openly, and Western labs are adopting them. The constraint has, ironically, produced tooling the whole field benefits from.
Links & Resources
External links — opens in a new tab
🇨🇳 China Desk Lead · Beijing, China
Reads the Mandarin sources first — DeepSeek, Qwen, Zhipu, and the rest.
The Casio fx-CG50: A Comprehensive Academic Treatise
by Richard Murdoch Montgomery
A 223-page deep dive into hardware architecture, statistical analysis, matrix operations, and Casio BASIC programming.
Electrophysiological Biomarkers of Neuropsychiatric Brain Dynamics Vol 1
by Richard Murdoch Montgomery
EEG-based biomarkers for schizophrenia and bipolar disorder — frequency band power, event-related potentials, and neural connectivity patterns.
The TI-84 Plus C Silver Edition
by Richard Murdoch Montgomery
A 609-page volume covering arithmetic, algebra, graphing, calculus, statistics, and programming on the TI-84 Plus C Silver Edition.
A Treatise on Functional Analysis
by Richard Murdoch Montgomery
Structures, dualities, and spectra — Banach spaces, Hilbert spaces, operator theory, and spectral decompositions for the working mathematician.
Comments
Open discussion — no account needed. Be respectful.
More from Chinese Models Desk
Meituan Gives Away LongCat-2.5, a 1.6T-Parameter Agent Model, Under MIT Terms
Meituan open-sourced LongCat-2.5, a 1.6-trillion-parameter multimodal MoE trained on domestic Chinese chips, under the MIT license with no revenue thresholds. The food-delivery giant is betting that permissive weights, not a token business, buy it a place in the developer toolchain.
DeepSeek Ships Its Whole App as an API: Search, Files, Voice and Mandatory Safety Checks on a $0.30 Flash Model
On November 13, DeepSeek exposed the features behind its consumer app through its API: server-side web search, file parsing, URL reading, OCR, ASR and TTS, all anchored on deepseek-flash. The price list and the compliance clause are the real story.
Baidu's ERNIE 5.5 Flash Preview Bets on 14B Active Parameters, With Apache 2.0 Weights Still a Promise
Baidu's 280B-total, 14B-active ERNIE 5.5 Flash arrives as an open base model and a Qianfan-hosted Preview, with a 1M-token context and Apache 2.0 weights reportedly due November 25. We separate what Baidu has documented from what is still a claim.